LinkedIn® does not describe a universal penalty for using AI to assist writing. Its current guidance welcomes content reflecting a real person’s expertise and says generic, repetitive material is less likely to be widely distributed. Review the substance, verify claims, and distinguish community feedback from policy enforcement or a proven ranking penalty.
Key takeaways
- The official guidance distinguishes useful assistance from low-substance output.
- An AI-slop analytics tip is not itself a removal or policy decision.
- Exact reach penalties need evidence beyond detector labels or anecdotes.
- Review facts, rights, perspective, and actual account behavior separately.
How to read the evidence
Search this question and you will find confident answers in both directions. Some say LinkedIn® punishes any AI-written post. Others say there is no penalty at all. Both camps tend to blur three different kinds of evidence, so this review keeps them apart.
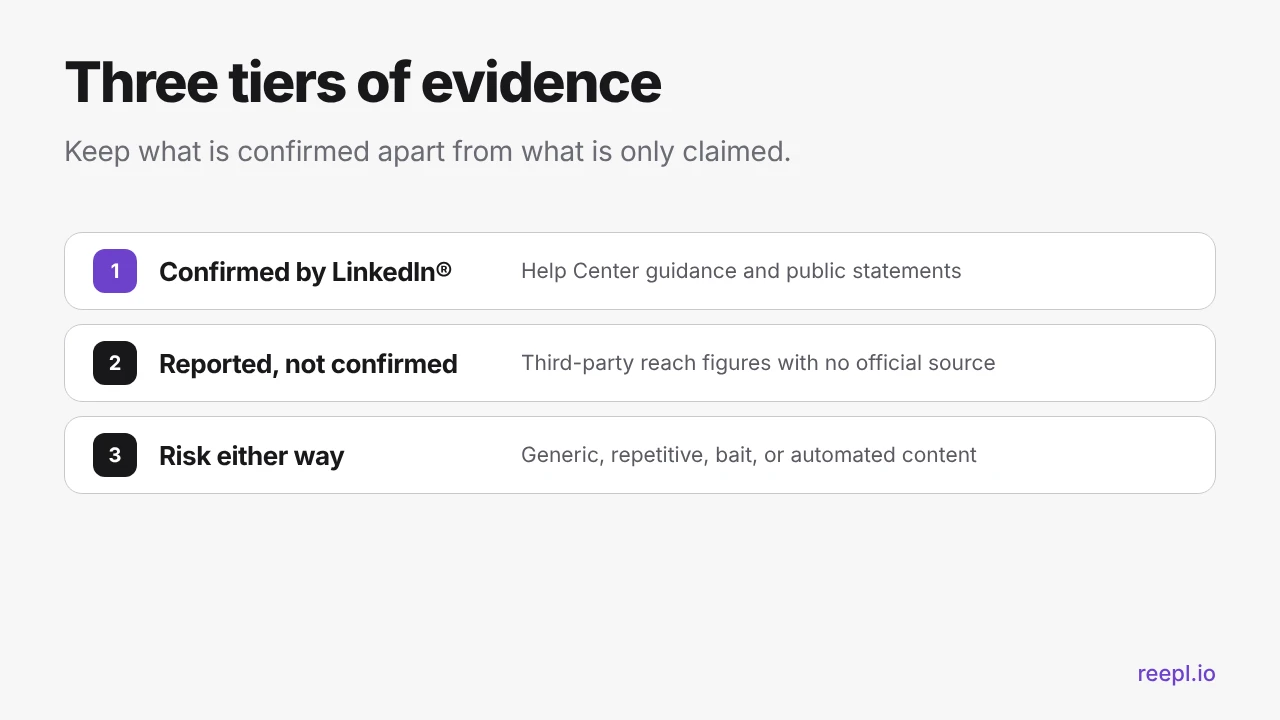
- Confirmed: things LinkedIn® has stated in its own help documentation or through its own executives.
- Reported but unconfirmed: claims from third-party sites, often with specific percentages, that LinkedIn® has not backed.
- Practical risk: problems that hurt a post whether or not any AI penalty exists.
What does LinkedIn® actually say about AI-assisted posts?
The official AI content help page, consulted in October 2026, says AI-assisted content is welcome when it reflects a real person’s perspective, experience, or expertise. It asks members to review, edit, and approve AI-assisted work and says members remain responsible for what they publish.
The same page says content that feels generic, repetitive, or lacks a clear point of view is less likely to be widely distributed. That is an explicit quality distinction. It does not establish a universal numerical penalty for all AI-assisted writing, and it should not be paraphrased as a promise that any edited post will receive normal reach.
The page defines “AI slop” as low-effort, likely AI-generated material that can look polished while lacking substance or perspective. It also describes a “Seems like AI slop” feedback option for posts and comments. This is now described in primary documentation, so a review does not need to rely on a screenshot or a report of an early rollout.
If enough community feedback is received, the help page says a tip can appear in post analytics. It explicitly says that receiving the tip does not mean the post was removed or a policy decision was made. Feedback, distribution, and enforcement are therefore related subjects that must not be collapsed into one claim.
The page recommends letting others know when you relied heavily on AI and that is not obvious from context. It does not provide a universal percentage threshold for “heavily.” Choose disclosure based on whether the assistance materially affects what readers would otherwise assume about authorship, media, or first-hand experience.
What do exact penalty claims fail to establish?
A claim that AI posts receive a fixed reduction in reach needs a clear method. How did the researcher determine which posts used AI? Did the comparison account for topic, audience, account size, format, and publication period? Were posts observed for the same amount of time? Without those answers, an impressive percentage can hide an uncertain classification.
A text detector cannot automatically settle the classification problem. A human may use formulaic language; an AI-assisted post may be heavily revised. If the detector mislabels those cases, the study can compare groups that do not represent the drafting methods its headline describes.
Even accurate labels would not make the comparison causal. Authors who use AI heavily may also post more frequently, select different subjects, or publish more templated material. The practical question is whether assistance produced useful, truthful work. The public sources here do not isolate a single reach effect caused solely by the presence of AI in the writing process.
The practical risks that exist with or without a penalty
Even if LinkedIn® never ranked a single post differently because of AI, these four problems would still cost you reach, replies, and trust.
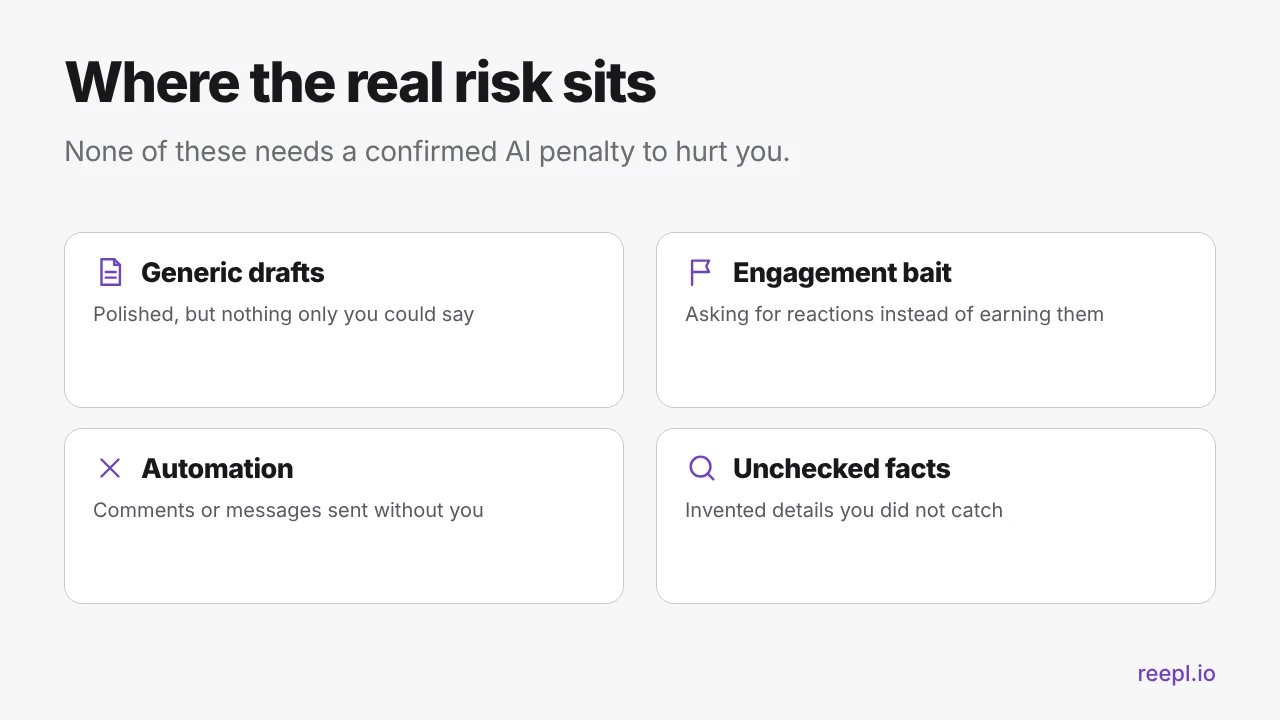
Generic, repetitive drafts
A model that has never seen how you write defaults to the safest, most average phrasing it knows. The result is the same question hook, the same three bullet points, and the same tidy lesson that thousands of other accounts publish. Readers do not need to identify AI to scroll past it. They just register that nothing in the post could only have come from you. For a fuller diagnostic, see how to tell when a LinkedIn® post sounds like AI, and for what makes drafting feel human, read can AI write LinkedIn® posts that sound human.
Engagement bait
"Agree? Comment YES below." AI drafts reach for this closer by habit. It asks for a reaction instead of earning one. Whether a human or a model wrote the bait line, it is a weak ending, and readers have seen it thousands of times.
What is different about account activity?
Writing assistance and account actions are different subjects. LinkedIn®’s automated activity guidance restricts third-party software and extensions that scrape, modify the appearance of, or automate activity on the website. The User Agreement provides the broader terms. A claim that a tool acts at a “safe” rate does not override those restrictions.
For engagement, keep the person responsible for reading the conversation, deciding what to say, and sending the reply. This is a control boundary, not a claim that every manually operated tool is approved or risk-free. Evaluate the actual tool behavior and the platform’s current rules.
Unchecked facts and invented details
An AI-assisted checklist that keeps the risk low
None of this requires avoiding AI. It requires keeping your judgment in the process. Use this checklist before any AI-assisted post goes live.
- Start from something real. A story, a client question, a rough voice note, or an opinion you hold. Prompting from a blank page is how generic drafts begin.
- Draft in your voice, not a default voice. Use a tool that works from your own writing. If you are still working out what your voice is, start with how to find your LinkedIn® voice.
- Add one detail only you could add. A date, a number from your own work, a name you have permission to use, a sentence you would actually say out loud.
- Take a position. Cut the "on one hand, on the other hand" hedging and say what you think.
- Remove the bait. Delete "Thoughts?" closers and engagement prompts that do not come from a real question you want answered.
- Verify every claim. Check each statistic, quote, and name against its source. If you cannot verify it, cut it.
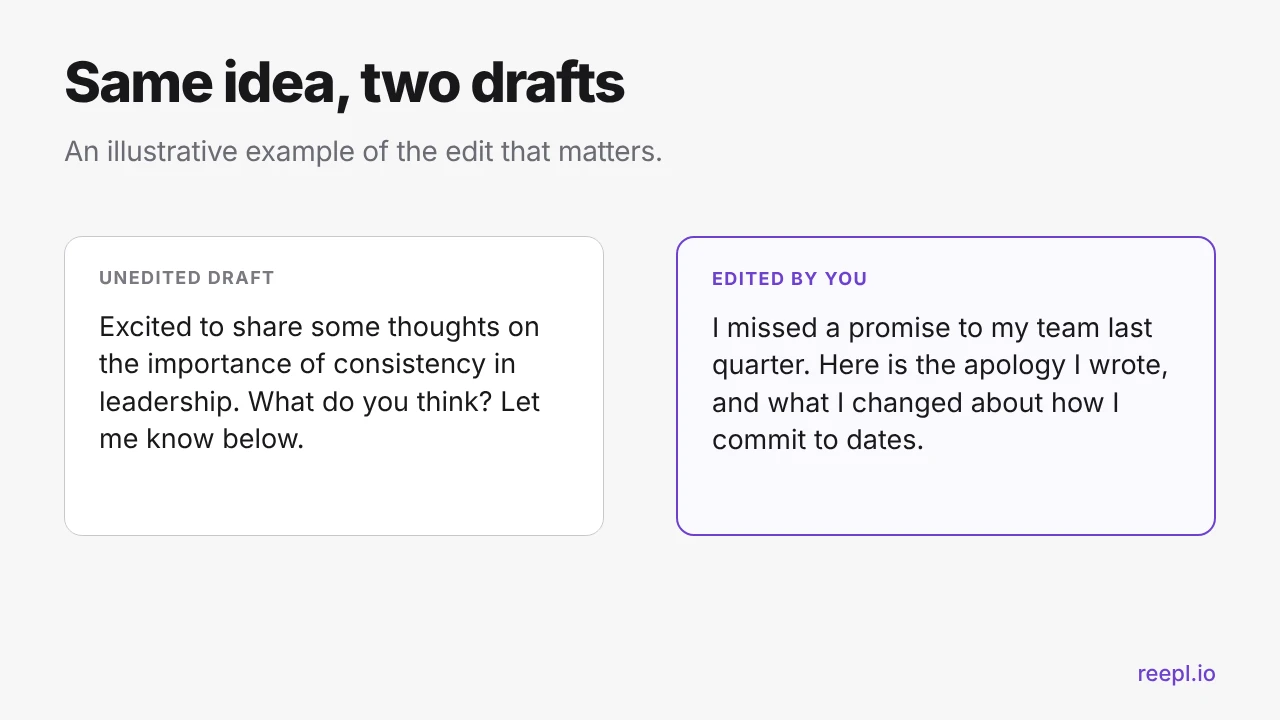
The edit that matters most is usually small. Here is what it looks like in practice.
If you want a quick second opinion before you post, the free AI Slop Detector for LinkedIn® marks the lines that read machine-written and suggests rewrites. It is a drafting aid, not a prediction of how LinkedIn® will rank the post.
How can Reepl support a reviewed writing process?
Reepl is an AI writing platform that puts your social media on autopilot in your own voice: it finds what to post about, drafts your posts, and keeps your calendar full, with you choosing what it does without asking.
Use Reepl to organize a genuine idea, guide the draft with your voice preferences, and keep your own content in a manageable publishing workflow. You choose review and scheduling settings. A voice profile guides expression; it does not prove factual accuracy or guarantee reach.
For comments and messages, Reepl drafts and you review, edit, and send. Keep personal anecdotes and evidence grounded in material you supplied. If the model adds an event or outcome, remove it unless you independently confirm it. Check current plans for product access rather than relying on an old quota quoted in a blog.
The useful result is a post you can stand behind. No writing platform, including Reepl, can promise how LinkedIn® will distribute a particular post or make it immune to policy review.
How do you review a post after an AI-slop feedback tip?
Read the tip as feedback on reception, then inspect the post. The official explanation says the tip does not itself mean removal or a policy decision. Do not assume it identifies the drafting tool, the amount of AI assistance, or the exact reason each person responded.
Start with the promise. Does the opening suggest an insight the body never delivers? Next, inspect the perspective. Could the same text appear under dozens of unrelated authors? Then check the evidence: is there a concrete explanation, source, or experience the author is entitled to share? A polished post can fail all three checks.
If the post contains an error, correct the error and make the correction understandable. If the issue is generic advice, decide whether an edit can add meaningful substance or whether the idea needs a new, better-developed post. Do not repeatedly delete and repost variants to guess how the feedback system behaves.
A useful response is to improve the next brief. Supply the actual decision, the relevant audience, the evidence, and the limitation. Ask the assistant to flag missing facts rather than inventing a personal anecdote. Keep a record of what you changed so the review becomes learning, not merely anxiety about a label.
What does an evidence-led rewrite look like?
Here is an illustrative example. A generic draft says: “The future belongs to leaders who embrace change. AI is transforming every industry, and the time to act is now.” It expresses urgency but gives the reader no situation, decision, or evidence. The problem is not a particular adjective. The post has little to explain.
Assume the author’s real note is: “Our team had trouble deciding whether to use AI for meeting summaries because some meetings contain confidential material.” A stronger draft would say: “Before choosing a meeting-summary tool, decide which meetings should never be recorded. We separated public project updates from conversations containing confidential customer details. The tool comparison came second. If your team has not agreed on recording permissions and data handling, a better summary will not resolve that gap.”
That revised version is still illustrative; the author may use it only if those events actually occurred. If they did not, change the frame: “A team evaluating meeting summaries should first decide which meetings must remain unrecorded.” The recommendation can remain useful without borrowing a fictional first-person experience.
The stronger version names a decision, explains its reasoning, and shows a boundary. It does not need a promised productivity gain or an assertion about what every organization should do. A reader can disagree with the recommendation or apply it to a real procurement conversation.
Now conduct a fact pass. Did the team actually separate those meeting categories? Is the policy approved for public discussion? Does the wording imply a privacy guarantee the tool does not provide? A style pass alone would miss those questions. Review the factual meaning before tuning the rhythm.
Why are detector scores a poor publishing objective?
A detector estimates authorship from patterns; it does not verify whether a post is useful, true, or yours to publish. Editing to reduce a score can produce unnatural language without improving any of those qualities. It can also distract you from a fabricated quotation or an unsupported claim.
OpenAI’s classifier notice says the company withdrew its text classifier in July 2023 because of low accuracy. This is a historical example with a specific scope. It is not evidence that every modern detector is identical, and it does not reveal LinkedIn®’s internal systems. It supports the narrower point that detector output requires caution.
The Professional Community Policies focus on conduct and content, including misleading claims and spam. A low detector score does not establish compliance with those rules. A high score does not prove the author used AI, copied a source, or lacks genuine expertise.
Use a writing diagnostic to identify vague language if it helps, but judge the suggestions yourself. The AI Slop Detector is an editorial aid, not a platform-risk score or a certificate of human authorship. For a more durable improvement, use the voice-brief process and maintain real source notes.
How can you investigate a reach change without blaming the wrong cause?
First, define the change precisely. A post receiving fewer impressions than an unusually successful predecessor is different from a sustained decline across comparable posts. Record the dates, subjects, formats, audience, and elapsed time at measurement. Check whether the comparison is between like-for-like observations.
Next, list plausible explanations. The topic may be less relevant, the opening may be unclear, the audience may be different, or the prior post may have benefited from a timely event. A change in drafting method can be one hypothesis without becoming the only explanation. Do not infer a hidden penalty solely because a post used AI and performed poorly.
Read the material as a prospective reader. Does the new post repeat something familiar? Does it contain an original explanation or merely restate a trend? Does it ask for attention before giving any value? These are actionable problems regardless of whether the platform classified the post in a particular way.
If you want to compare drafting workflows, keep the task comparable and record the amount of review. An unedited generic draft and a carefully researched human post differ on more than AI use. A more useful comparison asks whether assistance helps you produce equally accurate, specific work with less editing effort. Audience performance can be a secondary observation, with the limits stated.
Avoid attributing a change to a single word or punctuation mark. Organic distribution is not a controlled laboratory. A post revised after publication also has a different exposure history, so its later performance cannot cleanly show whether the edit removed a supposed trigger.
Finish the investigation with a decision you can support. You may choose to supply better source notes, reduce repetitive topics, improve the opening, or spend more time reviewing claims. “We do not know why this post traveled less widely” is a valid conclusion. It is more useful than a confident explanation that encourages you to fix the wrong part of the process.
Document what would change your view. A clear platform statement, an account notification with specific grounds, or a well-designed study may justify revising the explanation later. Until then, keep the distinction between observed performance and inferred cause visible in your notes and in any advice you share with others.
Keep the evidence review separate from reassurance. A useful process reduces avoidable mistakes, but no editor can promise a particular distribution outcome. Check the current platform guidance again when making a consequential decision, especially if an account notification identifies a specific issue.
What should you do before your next AI-assisted post?
Bring a real idea and enough context to explain it. Use AI for the part it can help with, then verify the facts, refine the perspective, and review the public meaning. Disclose substantial assistance where appropriate, especially if the reader might otherwise infer a human action or first-hand experience that did not occur.
Treat distribution changes as something to investigate, not a verdict about a drafting tool. The platform’s stated distinction is usefulness and perspective. A better draft and a clearer evidence trail are more productive next steps than chasing an unverified penalty percentage.
What should you tell a teammate who asks whether AI is allowed?
Answer with the actual distinction in the current guidance. Assistance is welcome when the content reflects a real person’s perspective and expertise; generic, repetitive output is treated differently. Then explain the team’s own editorial expectations for evidence, permissions, and review.
Avoid reassuring the teammate that a particular tool, phrasing pattern, or manual click makes everything safe. That would conflate content quality, account behavior, and enforcement. Give them a concrete review checklist and a route for resolving uncertain claims. The useful outcome is a draft the author understands and can support, together with a publishing workflow that respects the platform’s rules.
| Question | What the source establishes | What remains unproven |
|---|---|---|
| Is assistance allowed? | The AI help guidance welcomes real perspective and expertise. | A guarantee of distribution for any edited draft. |
| What does feedback mean? | An analytics tip is not itself a policy decision. | A precise ranking weight for each member report. |
| What about account actions? | Platform rules restrict specified third-party activity. | Any supposedly safe daily automation quota. |
| Can a detector settle it? | A detector produces a classification estimate. | The platform’s internal score or the truth of the post. |
Turn a useful idea into a clear draft
Bring your own context, review the draft, and keep the final wording yours.