LinkedIn® documents personalized feed ranking and the use of dwell time, comments, and other signals, but it does not publish a complete creator formula. Prioritize relevant, useful posts and distinguish confirmed mechanisms from benchmarks and folklore. Test your account carefully without treating correlations, fixed windows, or AI detector scores as ranking rules.
Key takeaways
- Dwell time is documented; a universal dwell threshold is not.
- Feed ranking is personalized rather than one score for every reader.
- No cited source establishes fixed comment multipliers or a universal link penalty.
- Measure comparable posts and separate audience response from causal claims.
What does the evidence actually establish?
LinkedIn® feed ranking uses personalized predictions about relevance and member behavior. Public engineering documentation describes parts of that system, but it does not provide a complete creator recipe with fixed weights for comments, saves, links, or post length. Treat the documentation as evidence of mechanisms, not as a promise about your next post.
The strongest source for this guide is the platform’s October 2024 engineering article, Leveraging Dwell Time to Improve Member Experiences on the LinkedIn® Feed. It explains a two-pass architecture and several objectives used in ranking. It also describes why simple universal time thresholds were inadequate. That is materially different from a creator checklist claiming that every post must pass the same timed test.
The policy and help pages cited here were consulted in October 2026. Their wording can change. The engineering article is older, and its age matters: it confirms the documented design at that time, not that every implementation detail remains identical. Where a current weight or threshold is not public in these sources, we do not invent one.
This article contains no Reepl dataset study and makes no measured reach claims. The practical suggestions are editorial recommendations based on the documented mechanisms and on sound measurement practice. You can use them to choose better questions to test, without mistaking them for privileged knowledge of the ranking system.
| Claim | Evidence status | Practical implication |
|---|---|---|
| Dwell time contributes to ranking | Documented in the October 2024 engineering article. | Make the post useful to read, including for people who never react. |
| The feed ranks for individual viewers | Documented architecture and objectives. | Write for a recognizable reader and professional interest. |
| Every comment has a fixed value relative to a like | No fixed creator multiplier established by the sources here. | Do not calculate a strategy from invented weights. |
| AI assistance alone creates a universal penalty | Not the policy stated in the AI help guidance. | Evaluate substance, perspective, and review. |
| One length or publishing hour wins everywhere | Not established by these primary sources. | Test your own audience and task. |
How does the documented ranking architecture work?
The October 2024 engineering description says the feed mainly uses a two-pass funnel. First-pass systems retrieve candidates, including content from a member’s network and out-of-network recommendations. A second pass ranks the accumulated candidates using multiple predictive objectives. The output is a personalized order for a particular viewer.
That description explains why a post does not have one universal score shared by all readers. A useful technical explanation may be highly relevant to one professional and uninteresting to another. The creator’s task is to make the intended subject and value clear, while recognizing that distribution depends on context outside the creator’s control.
The article describes viewer-side objectives, downstream effects on the viewer’s network, and feedback value to creators. Active behaviors include comments and reshares; passive behaviors include clicks and dwell time. It does not give a public table that lets you add those actions together into a reliable reach forecast.
Avoid turning a simplified diagram into a literal sequence that every post must complete. “Quality check, small test audience, wider distribution” can be a useful teaching model, but it is not the same as the engineering architecture documented here. A model becomes misleading when someone attaches precise minutes or audience thresholds without supporting evidence.
For your next post, name the reader and the job the post helps them do. A security engineer evaluating a migration needs different context from a founder approving the budget. You can explain the same event to both audiences, but trying to satisfy both in an unclear opening often weakens the explanation.
What does dwell time mean for a writer?
Dwell time is the time a person spends viewing content before moving on. The engineering article explains how passive consumption helps the system learn from people who read without explicitly reacting. It describes both predicted skipping and a normalized approach to longer dwell behavior.
The normalization is important. Different formats and distribution contexts have different time patterns. The article explains that a fixed universal threshold can bias recommendations toward content types that naturally take longer to consume. Its approach tries to identify valuable attention within relevant categories rather than simply reward the longest possible post.
That is not an instruction to pad your writing, split every sentence onto a new line, or hide the answer until the end. The same article explicitly discusses limiting clickbait and dwell bait. Extra reading time caused by confusion is not the same thing as a useful experience, and the public description does not promise a reward for either tactic.
A practical writing check is whether each paragraph advances the reader’s task. A process post may need an example and an exception. A short announcement may need only the change and its consequence. Length should follow the explanation required. Cut repetition, but keep the condition that prevents readers from misusing the advice.
You usually cannot observe the platform’s internal dwell predictions in your own analytics. Do not invent an estimate by dividing impressions by reactions. Instead, assess the usefulness of the format through reader questions, relevant responses, and the purpose of the post. Those observations support editorial decisions even when they cannot reveal the ranking model.
What can reactions, comments, and reposts tell you?
Visible reactions and conversations show how some readers responded. They do not expose every reason the feed distributed the post. A post can receive many impressions before its comments arrive, and more distribution itself creates more opportunities for comments. That makes simple correlations difficult to interpret.
A substantive comment can reveal whether the audience understood the claim, noticed an exception, or wants more detail. A repost can show that someone found the post worth sharing with their network. Neither action gives you a universal conversion into additional impressions. Do not repeat unsupported statements that a comment is worth a fixed number of likes.
Read the conversation before deciding a post succeeded. A controversial error can attract many corrections. A relevant buyer may quietly read an explanation and contact you later. If your only target is visible activity, those cases can look backwards. Include business relevance and accuracy in the review.
Invite discussion when a real question remains. For a decision guide, ask which constraint changes the recommendation in the reader’s situation. For a tutorial, ask where the process breaks down. Avoid demanding a keyword or a ceremonial agreement solely to manufacture activity.
You can use the guide to meaningful comments to improve your replies. The purpose is to add to the conversation. Treat your response as professional communication, not as a way to trigger a secret distribution step.
Are external links, timing, and post length ranking rules?
The sources used here do not establish a universal penalty for every external link, a single best publishing hour, or a required character range. Third-party studies may describe patterns in their samples, but sample results are not a published platform specification. Before using a benchmark, inspect what was measured and what alternatives were controlled.
A link changes the reader’s task. A post that summarizes a useful resource and provides its source is different from a post that says little except “read this.” If the goal is visits to a research paper, a useful click may matter more than maximizing feed impressions. Hiding the link can make verification harder without proving any distribution benefit.
Publishing time is also a practical question. Your audience’s working hours and your availability to answer can guide a first schedule. A global benchmark does not know whether your readers are shift workers, international executives, or practitioners who read after work. Keep the timezone in every observation.
For length, distinguish density from brevity. A short post can be vague, and a long post can be useful. Write enough to explain the decision and its most important limitation. Use a clear opening to make the subject apparent rather than treating an arbitrary character count as the objective.
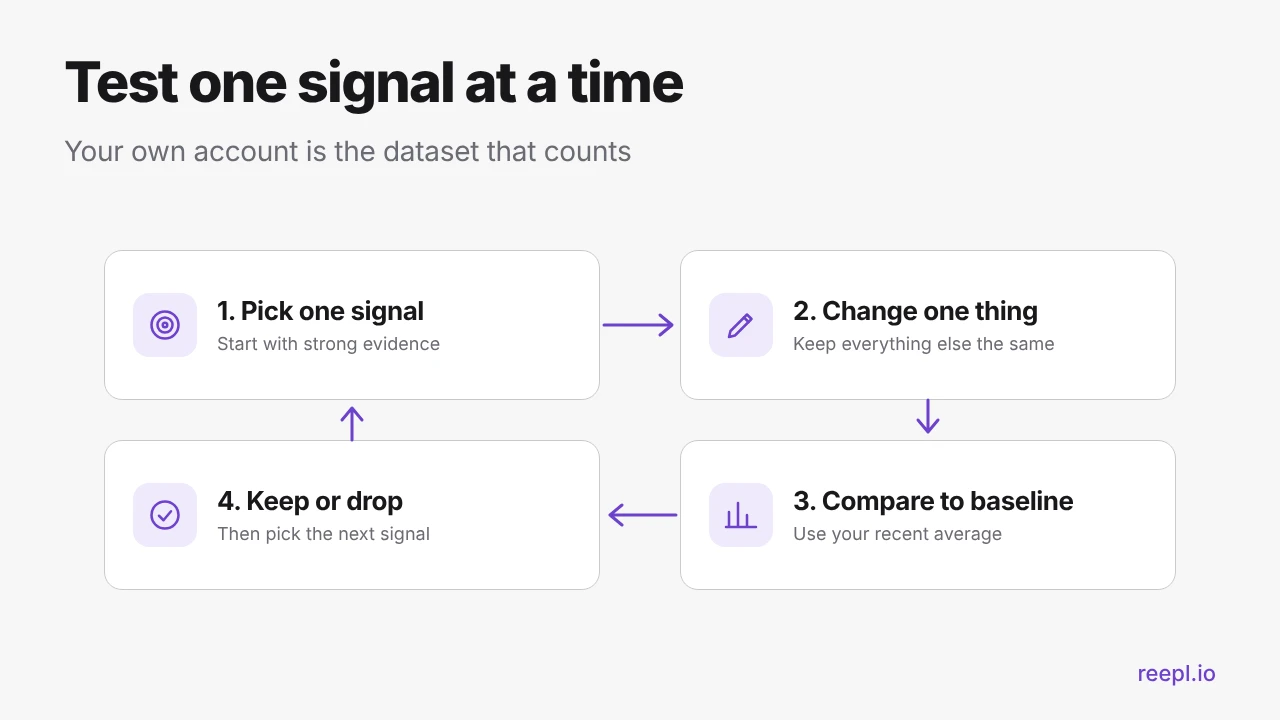
Test one decision at a time when possible. If you change topic, format, timing, hook, and link placement together, the result cannot tell you which change mattered. Even a careful sequence of organic posts remains an observational comparison, because audiences and platform conditions differ.
How does AI-assisted content fit the evidence?
The current LinkedIn® AI content guidance, consulted in October 2026, distinguishes assistance that reflects a person’s perspective from generic, repetitive content lacking substance. It says AI-assisted content is welcome when it reflects real perspective, experience, or expertise, and that generic content is less likely to be widely distributed.
That is a quality distinction, not a published universal percentage penalty for using a model. The guidance also describes feedback labeled “Seems like AI slop” and says an analytics tip based on community feedback does not itself mean the post was removed or a policy decision was made. Do not turn the existence of feedback into an unsupported claim about exact ranking weights.
Review the draft’s substance before its style. Check whether the example happened, whether the source supports the claim, and whether the conclusion is yours. A human-written generic post can be weak; an AI-assisted explanation can be useful. Removing a word associated with AI does not repair a false statement.
Third-party detector results are not the platform’s internal scores. OpenAI’s historical classifier notice records that its classifier was withdrawn in July 2023 because of low accuracy. That does not evaluate every current detector, but it is a reason not to use an authorship label as evidence of how LinkedIn® ranked a post.
Use drafting help for organizing an idea, producing alternatives, or editing repetition. Keep the factual source material and final judgment with you. A voice profile can guide wording; it cannot provide experience you never had.
Which engagement tactics conflict with platform rules?
The Professional Community Policies prohibit artificial engagement and tell members not to agree in advance to like or reshare each other’s content. The same policy addresses spam and unwanted promotional communication. A coordinated exchange of reactions is therefore not simply a different content strategy.
The automated activity help page and User Agreement address prohibited third-party behavior. Do not infer permission from somebody claiming a low daily volume is safe. A daily quota does not override the nature of an action or the platform’s rules.
Separate your own content publishing from engagement. Authorized scheduling of your own posts is a different workflow from software acting as you in comments, messages, connections, or likes. Reepl is an AI writing platform; it can assist with your own content workflow under your chosen controls, while engagement drafts are reviewed and sent by you.
If an account restriction occurs, follow the platform’s stated recovery instructions and investigate the actual tools connected to the account. Do not respond by trying to hide activity patterns or by repeatedly testing supposed safe limits. The goal is a professional account used within its rules, not a workaround for enforcement.
What does a defensible account-level experiment look like?
This is an illustrative measurement plan, not a result from Reepl or a client. Suppose a consultant wants to know whether decision checklists produce more useful conversations than broad opinion posts. The hypothesis concerns audience usefulness, not a secret algorithm preference for lists.
Choose a stable subject area and record the intended reader for each post. Keep format and publishing windows reasonably comparable. Label each post by type before publishing so a successful post is not reclassified after the fact. Record the question it answers, the evidence it uses, and any unusual event that could affect response.
Define the review window in advance. Capture impressions at the same elapsed point, plus substantive comments, relevant inquiries, and any source clicks you can measure appropriately. Do not mix a post observed shortly after publication with one that has circulated for weeks. Note what the dashboard actually reports instead of assuming every measure has the same definition.
At review, inspect the individual posts as well as the summary. One unusually topical post can dominate an average. If the checklist posts seem more useful, ask whether their topic or specificity explains the difference. The reasonable conclusion may be “this format deserves more trials,” not “the algorithm rewards checklists.”
Keep a practical stopping condition. If a test makes the posts harder to understand, creates misleading promises, or consumes too much time, stop. A measurement plan should support better communication. It should not require publishing weak work merely to complete an experiment.
What should you change first?
Start with the problem you can actually observe. If readers misunderstand the post, improve the explanation. If the wrong people respond, sharpen the audience and subject. If the content is accurate but hard to scan, improve structure. If a post gets little attention, compare several plausible explanations before blaming one ranking signal.
Keep a short evidence note beside any advice you adopt: the source, its date, what it establishes, and what remains unknown. A primary source about a mechanism is more useful than an unattributed multiplier. A modest experiment on your account is more informative than a dramatic claim you cannot reproduce.
The next action is simple: choose one upcoming post and make its reader, claim, evidence, and limitation explicit. Publish through your chosen authorized workflow, answer genuine responses, and review it alongside comparable work. That is a process you control even when the feed’s exact ranking weights remain private.
How should you read a third-party algorithm study?
Begin with the population. A study of posts connected to one analytics service may overrepresent active creators, certain industries, or particular account sizes. That does not make the study useless. It changes the question from “what always works?” to “what pattern appeared in this sample?”
Next, check the unit of analysis. A post-level average and an account-level average can tell different stories. A few large accounts may contribute many high-reach posts. If the study mixes personal profiles and company Pages, or organic and paid distribution, the combined result may not describe your situation.
Look for the observation period and metric definitions. A recent report may analyze older posts. Impressions, unique viewers, engagement rate, and link clicks answer different questions. If the denominator is unclear, a rate cannot be compared responsibly with your own reporting.
Finally, inspect the language of the conclusion. “Posts with documents received more reactions” is an association. “Documents caused the feed to promote those posts” requires stronger evidence. Topic, author reputation, audience size, and effort invested in the asset may explain part of the difference. Keep the useful hypothesis and remove the unsupported causal promise.
Before adopting the finding, write one sentence about how your account differs from the sample. Then choose a low-cost trial that still produces useful content for your readers. You do not need to reject all outside research. You need to preserve its scope when translating it into a publishing decision.
What belongs in a ranking evidence note?
Write the claim in the narrowest form the source supports. Record the publication date, source type, population if relevant, and the proposed action. Then add the uncertainty you must preserve. For example, an engineering paper can establish that a signal was modeled without revealing its current production weight.
Keep that note attached to the recommendation when sharing advice with a teammate. Otherwise, “worth testing for this audience” can gradually become “the algorithm requires this.” Revisiting the original note prevents a reasonable experiment from hardening into an unsupported rule that later writers repeat as fact.
Turn a useful idea into a clear draft
Bring your own context, review the draft, and keep the final wording yours.